Choose a base model
Krea 2, FLUX, Qwen Image and Z-Image suit different looks. Your LoRA is fine-tuned on the one you pick.
 Loras AI
LoRAs, fine-tuned on your images.
Loras AI turns 4–30 of your images into a LoRA: a lightweight fine-tuned model that keeps your character, product or style consistent in every new image. No GPU, no code.
Quick answer: Train supported image and video LoRAs with configured services, sufficient credits and a compatible dataset. Each LoRA must use its paired generator; catalog listings do not establish compatibility.
A small, focused dataset is enough to train a LoRA.
Presets for the three things people fine-tune most.
FLUX, Krea 2, Qwen Image and Z-Image, plus Wan and LTX video families.
Review every caption and the trigger word before training.
Follow training progress and reuse finished models.
Credit costs are shown before you submit anything.
Training and generation run in the cloud.
English, 中文, 日本語 and 한국어.
Images and videos generated with Loras AI Image and Loras AI Video. Click one to use its prompt.
These original images were AI-generated as concept references. They are not Loras AI training outputs, before/after comparisons or evidence of model performance.
Three steps from your images to a fine-tuned model you can reuse.
Add 4–30 clear images of one character, product or style. Review each image and caption before you train.
Pick a base model and start fine-tuning. Your LoRA trains in the cloud; follow its progress in My LoRAs.
Generate new scenes with your fine-tuned model while your subject stays the same.
Everything you need to fine-tune a model, without setting up hardware or writing code.
| Feature | Loras AI | Train locally | Developer APIs |
|---|---|---|---|
| Needs your own GPU | No | Yes, high VRAM | No |
| Needs coding | No | Environment setup | Yes |
| Dataset and caption tools | Built in | Separate tools | Build your own |
| Generate after training | Same workspace | Separate setup | Build your own |
| How you pay | Credits per task | Hardware and power | Per-request billing |
Krea 2 connects cloud training to image generation. MOSS and Anima offer separate generation workflows, alongside video model exploration and draft tools. Training and generation require sign-in and sufficient credits.
Each model needs compatible LoRA weights; adapters are not interchangeable. Resolution options and credit costs appear in the generation workspace.
Costs and limits below follow the application configuration. Integration describes the code, not verified provider uptime or a successful live training run.
| Model | Integration | Cloud input limits | Credits and settings | Output and compatibility |
|---|---|---|---|---|
| Krea 2 | Integrated; configuration required | 1–30 JPEG, PNG or WebP images with captions and a trigger phrase. Up to 15 MiB per image; 25 MiB total. | Training: 100 credits / task. Generation: 10 credits / image. Fixed training steps: 100. | LoRA weights after success; use the paired Krea 2 generator. Compatibility with other base models is not implied. |
| FLUX.1 Dev | Integrated; configuration required | 4–30 JPEG, PNG or WebP images with captions and a trigger phrase. Up to 15 MiB per image; 25 MiB total. | Training: 167 credits / task. Generation: 10 credits / image. Fixed training steps: 500. | LoRA weights after success; use the paired FLUX.1 Dev generator. Compatibility with other base models is not implied. |
| FLUX.2 Dev | Integrated; configuration required | 10–30 JPEG, PNG or WebP images with captions and a trigger phrase. Up to 15 MiB per image; 25 MiB total. | Training: 2134 credits / task. Generation: 14 credits / image. Fixed training steps: 1000. | LoRA weights after success; use the paired FLUX.2 Dev generator. Compatibility with other base models is not implied. |
| Qwen Image 2512 | Integrated; configuration required | 4–30 JPEG, PNG or WebP images with captions and a trigger phrase. Up to 15 MiB per image; 25 MiB total. | Training: 167 credits / task. Generation: 10 credits / image. Fixed training steps: 500. | LoRA weights after success; use the paired Qwen Image 2512 generator. Compatibility with other base models is not implied. |
| Z-Image Turbo | Integrated; configuration required | 4–30 JPEG, PNG or WebP images with captions and a trigger phrase. Up to 15 MiB per image; 25 MiB total. | Training: 209 credits / task. Generation: 10 credits / image. Fixed training steps: 500. | LoRA weights after success; use the paired Z-Image Turbo generator. Compatibility with other base models is not implied. |
| Wan 2.2 | Integrated; configuration required | 3–10 MP4 clips with a trigger phrase. Up to 8 MiB per clip; 24 MiB total. | Training: 1667 credits / task. Generation: 67 credits / 5-second video. Fixed training steps: 100. | LoRA weights after success; use the paired Wan 2.2 generator. Compatibility with other base models is not implied. |
| LTX-2 19B | Integrated; configuration required | 3–10 MP4 clips with a trigger phrase. Up to 8 MiB per clip; 24 MiB total. | Training: 584 credits / task. Generation: 34 credits / 5-second video. Fixed training steps: 500. | LoRA weights after success; use the paired LTX-2 19B generator. Compatibility with other base models is not implied. |
Cloud tasks require sign-in and sufficient credits. Krea 2 needs Fal; WaveSpeed image and video trainers need WaveSpeed access and R2 storage.
Cloud training sends your selected media and captions to the provider. Image and video dataset limits differ. Confirm account readiness before submitting.
A focused workflow
A LoRA is a lightweight fine-tuned model: instead of retraining a whole base model, it learns one character, style or product from a small set of images. Loras AI handles the dataset, captions and training, so a few images become a fine-tuned model you can reuse.
Krea 2, FLUX, Qwen Image and Z-Image suit different looks. Your LoRA is fine-tuned on the one you pick.
Check dimensions and repeats, and keep useful variety in angle, lighting and background.
Describe what changes between images so the fine-tuned model learns only your subject. Check the trigger word before training.
When training finishes, open it from My LoRAs and generate new scenes with your fine-tuned model.
Ideas worth teaching
Explore three ways to define a training concept. Each reference links to a dedicated workflow, with dataset advice and evaluation prompts.
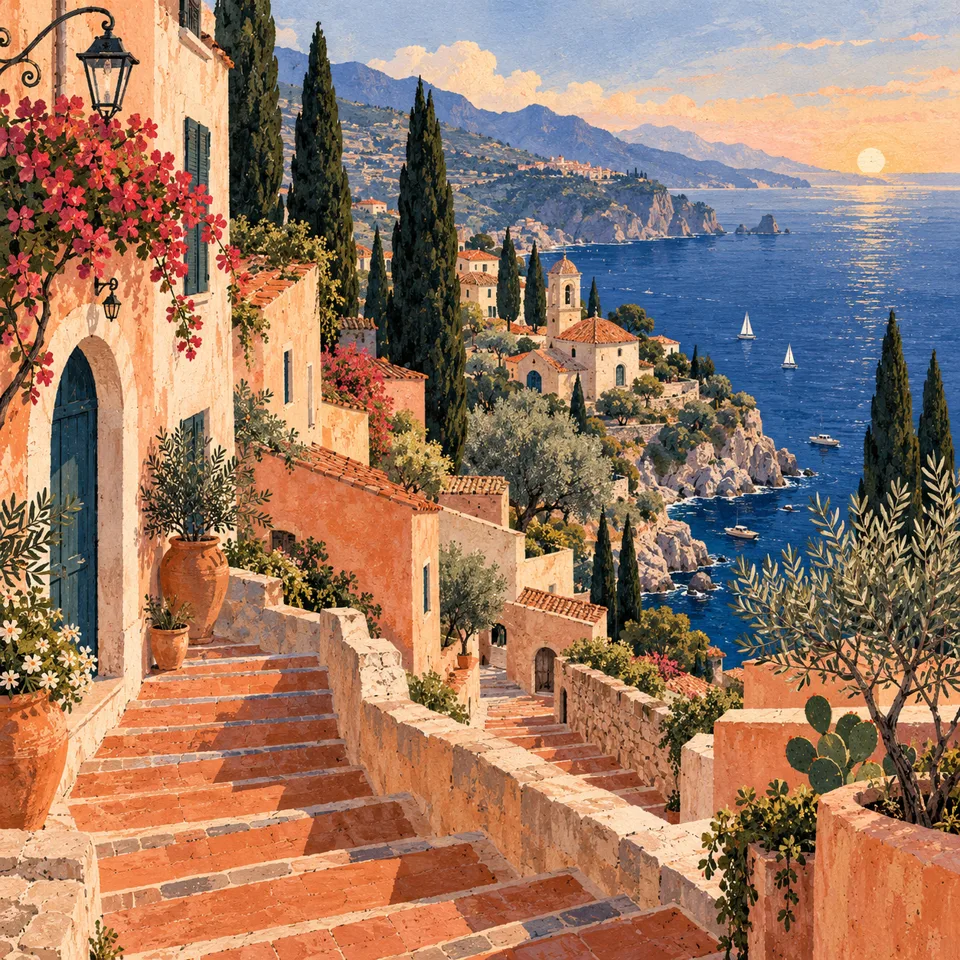
Use this coastal illustration as a visual-language reference. A style dataset should vary the subject while keeping its materials, colors and mark-making coherent.
Caption exampleA coastal village in ohwx_style, gouache texture, warm flat colors and fine ink contours.
Explore style LoRA training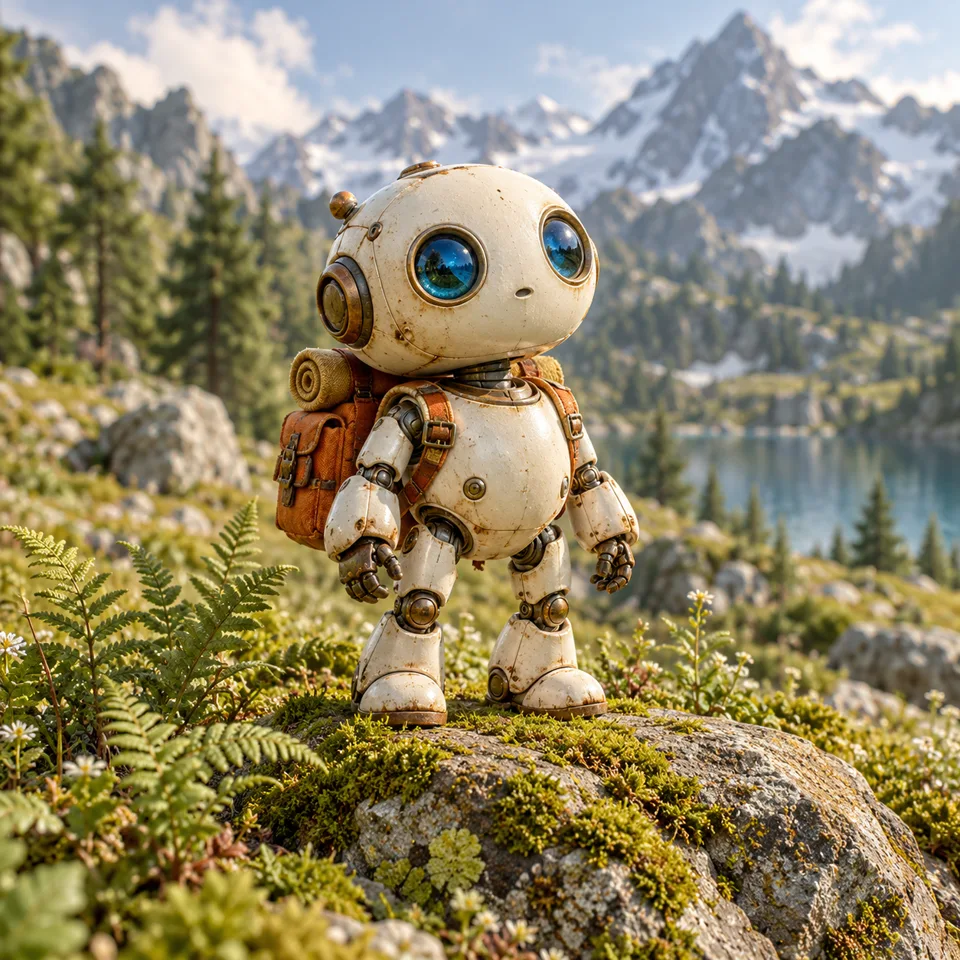
An original ceramic explorer gives a dataset a clear identity. Vary the angle, pose and surroundings instead of repeating one composition.
Caption exampleohwx_robot, a ceramic explorer with blue glass eyes, standing beside an alpine lake in daylight.
Explore character LoRA training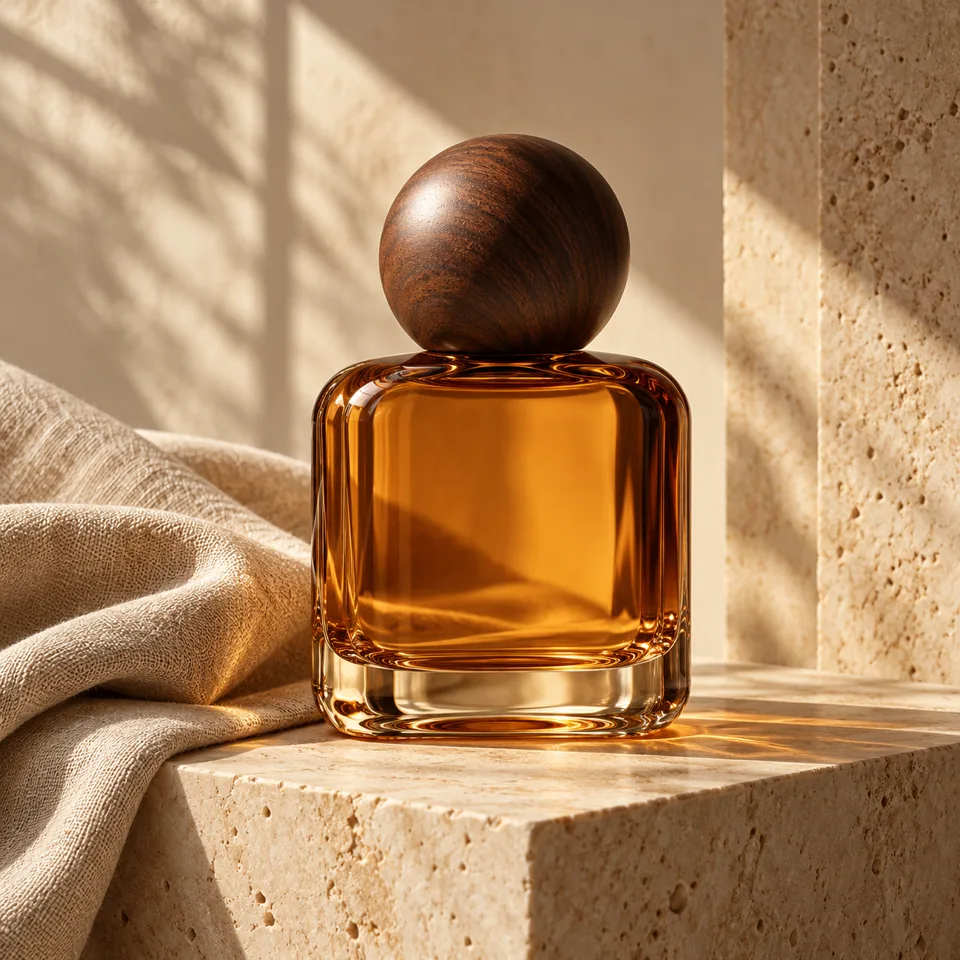
A blank amber bottle makes shape and materials easy to discuss. Include alternate views of its glass body and cap rather than teaching a single background.
Caption exampleohwx_bottle, an amber glass bottle with a round walnut cap, on a travertine surface in window light.
Explore product LoRA trainingThese original images were AI-generated as concept references. They are not Loras AI training outputs, before/after comparisons or evidence of model performance.
From intent to evaluation
Prepare the image or video dataset required by the selected model, review its trigger and captions, then submit training. Use the completed weights with their matching generator.
Decide whether you want a recognizable character, a transferable style, a distinctive product or a specific motion.
Read the noteKeep the intended concept consistent while varying details you do not want the model to memorize.
Read the noteInspect file dimensions, edit each caption and export the local configuration before leaving the workspace.
Read the noteTest completed, compatible LoRA weights with new prompts. Record the model, settings, successes and failures, and compare with the base model to evaluate the concept.
Read the noteDataset & compatibility
A LoRA is fine-tuned on one base model family and only works there. A FLUX LoRA will not load in Krea 2, Qwen Image or Wan, so choose the base model before you prepare images.
Read the dataset preparation notePrompt notebook
Save these ideas for evaluating a compatible trained adapter later. They are prompt examples, not generated results or a promise of consistent output.
A hillside library in ohwx_style, warm flat colors, textured paper and delicate ink contours.
A vintage desk lamp in ohwx_style, simple composition, warm ochre and indigo palette.
A quiet forest path after rain in ohwx_style, layered shapes, visible gouache texture.
A small sailboat in ohwx_style, bold simplified forms, soft paper grain, no lettering.
An original fictional gardener in ohwx_style, full-body pose, simple pale background.
A night market in ohwx_style, restrained blue and amber palette, hand-painted details.
Related notes
Practical reading on image selection, captions, training settings and evaluating what a model actually learned.
FAQ
Model-specific guidance, with the current availability stated clearly.
A LoRA is a type of fine-tuned model. Full fine-tuning retrains an entire base model; a LoRA trains a small add-on file instead, so it needs far fewer images and less compute, and it loads on top of its base model.
Open Train, pick a supported base model, upload 4–30 images of one subject and review the captions. The credit cost appears before you submit, and finished LoRAs show up in My LoRAs, ready to generate with.
Krea 2, FLUX.1, FLUX.2 Dev, Qwen Image, Z-Image, Wan 2.2 I2V and LTX-2 19B have training and paired generation integrations. Paid tasks require configured services, sign-in and sufficient credits. Other catalog models remain previews.
Local draft preparation processes images in the current browser tab; exported JSON excludes source files. Refreshing or leaving clears local images. Submitting cloud training sends the selected dataset and captions to the provider; WaveSpeed training also uses configured R2 storage for datasets and archived artifacts. Storage privacy depends on bucket access settings. Generation sends prompts and selected LoRA references to the relevant service. Only submit material you have permission to use.
Adapters are not interchangeable. Match the model architecture, base version and loading workflow. Krea 2, MOSS and Anima need their own compatible weights; similar names do not imply compatibility. Video workflows may also require multiple adapter files.
Keep exploring
Compare related model families before choosing a training workflow. Adapter formats and base-model versions must remain compatible.
Choose a compatible model, prepare images and captions, then submit an available training or generation workflow. You can also export a dataset configuration draft for free.
Bring 4–30 images. Leave with a LoRA that keeps them consistent.